I'm Ahmed Ali — a Computer Engineering student specializing in Data Engineering. I design end-to-end ETL pipelines, relational data models, and containerized architectures, and I integrate LLM/RAG systems on top of them.
I'm a Computer Engineering student at Pharos University in Alexandria (P.U.A.), with hands-on experience designing end-to-end ETL pipelines, relational data modeling, and containerized architectures using Docker, MySQL, and PostgreSQL.
Alongside my degree, I'm expanding into cloud data engineering through the DEPI Microsoft Data Engineer track, and I've contributed to an evidence-grounded clinical RAG system built during an AI hackathon — covering document processing, retrieval, and citation-verified answer generation.
I care about pipelines that are reliable before they're clever: schema normalization, encoding-safe parsing, and automated ingestion that doesn't break on messy real-world data.
A Data Engineer specializing in designing and building databases, developing data pipelines, and executing end-to-end ETL/ELT processes. I rely on tools like Python, SQL (MySQL, PostgreSQL), and Docker to handle complex, large-scale data efficiently — delivering clean, high-quality, scalable data solutions that support smart business decisions.
From raw data to relational storage — the languages and tools I use to move it, model it, and serve it.
Credentials that support my work across data engineering, pipelines, and AI-augmented systems.
I combine reliable data systems, algorithmic thinking, and AI-augmented retrieval to solve real problems — not just move data around.
Designing dependable ETL/ELT workflows, schema design, and warehouse foundations that keep data clean, consistent, and trustworthy.
Building efficient data structures and logic-driven applications — from stack-based evaluators to clean, dependable backend scripts.
Integrating LLM and RAG pipelines on top of structured data so retrieval stays grounded, citation-verified, and genuinely useful.
Expanding practical depth across the Big Data and cloud data engineering stack — the tools and concepts I'm actively building with right now.
Four projects spanning the pipeline: raw data ingestion, warehouse modeling, evidence-grounded retrieval, and interactive visualization.
A containerized ETL pipeline that extracts raw CSV data, cleans and standardizes it, and loads it into a MySQL database running in Docker — with schema normalization, encoding-safe parsing, and automated ingestion via SQLAlchemy.
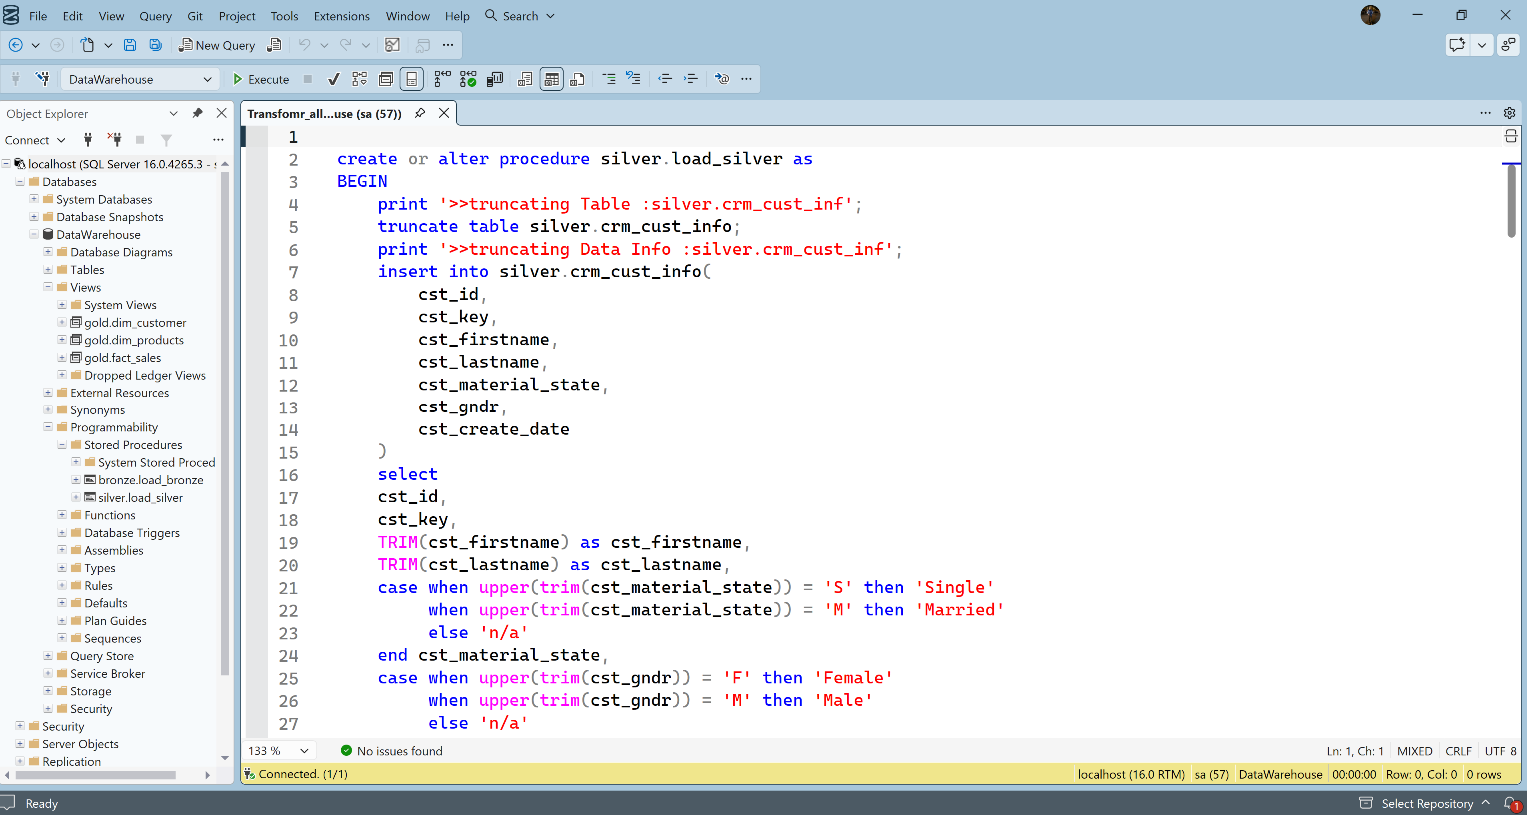
An end-to-end data warehouse in SQL Server that integrates CRM and ERP CSV sources through Bronze, Silver, and Gold layers — T-SQL load procedures, data cleansing and standardization, and a star-schema Gold layer (customer and product dimensions with a sales fact) ready for analytics.

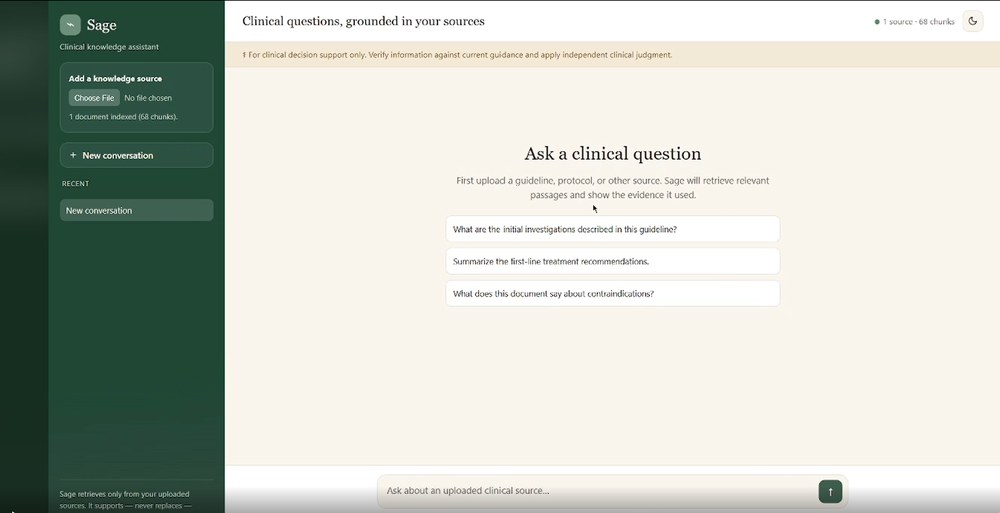
A clinical Retrieval-Augmented Generation system built during an AI hackathon — document processing, retrieval, and grounded answer generation from medical guideline sources, with citation verification. Local LLM execution via Ollama.

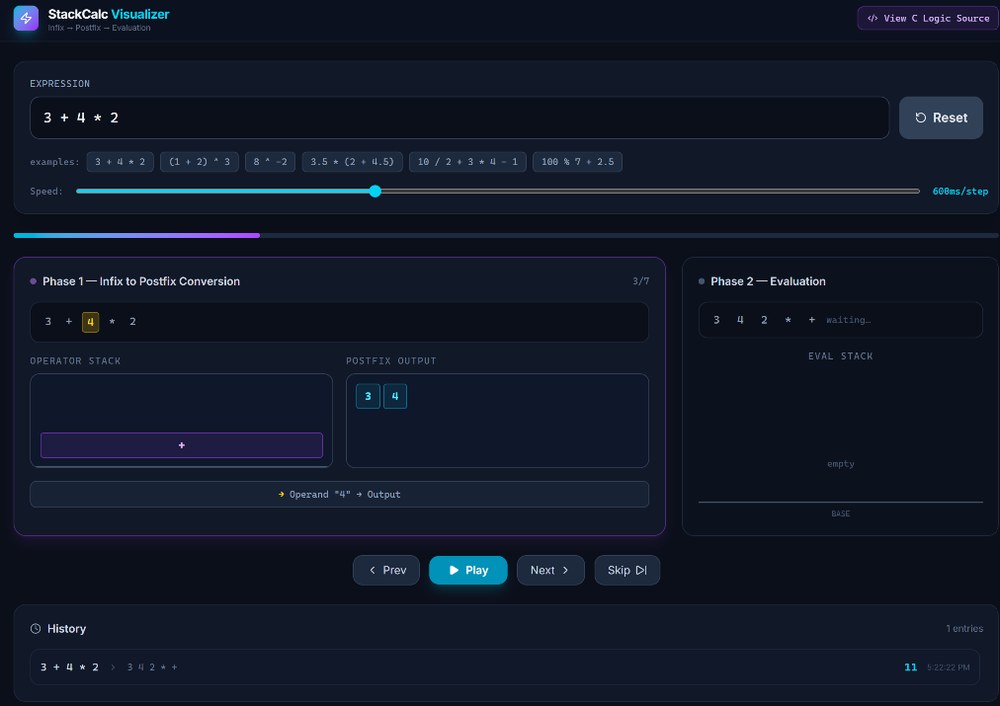
An interactive web application that visualizes infix-to-postfix expression conversion and step-by-step stack-based expression evaluation, with the core logic in JavaScript behind a React front end.